🏭 foundry — Claude Code Plugin
OSS Claude Code configuration for Python/ML projects: 10 specialist agents, 11 skills, event-driven hooks, and repeatable audit and calibration workflows.
Changelog records version-by-version changes, including the plugin's earlier directory history.
Contributing or want internals? See DEVELOPMENT.md.
Optional integrations:
/oss:reviewand/oss:releaseadd release/review workflows (requires theossplugin);/develop:featureand/develop:fixadd implementation workflows (requires thedevelopplugin);/research:runand/research:topicadd ML research workflows (requires theresearchplugin).
📋 Contents
- What is foundry?
- Why foundry?
- Install
- Quick start
- Current boundaries
- Git and GitHub approvals
- How foundry works
- Skills reference
/foundry:setup/foundry:audit/foundry:calibrate/foundry:manage/foundry:brainstorm/foundry:investigate/foundry:profile/foundry:distill/foundry:session/foundry:create/foundry:humanizer- Agents reference
- foundry:sw-engineer
- foundry:solution-architect
- foundry:qa-specialist
- foundry:linting-expert
- foundry:perf-optimizer
- foundry:doc-scribe
- foundry:web-explorer
- foundry:curator
- foundry:challenger
- foundry:creator
- Agent relationships
- Rules installed
- Configuration
- Troubleshooting
- Plugin structure
- Bin helpers
- Upgrade
- Uninstall
- Auto-allow audit log
- Development / testing
- Contributing / feedback
🤔 What is foundry?
foundry is the configuration and workflow layer for Claude Code on Python/ML OSS projects. It gives Claude Code ten specialist agents, eleven namespaced skills, rules, and event-driven hooks for routing work, checking configuration, measuring instruction quality, and recording lessons for review.
The problem it solves is workflow drift: a generalist session can mix architecture, implementation, tests, docs, and tooling without clear ownership, while corrections disappear between sessions. Foundry provides explicit role boundaries, repeatable audits and calibration runs, and project-local state for the parts it supports. It does not replace application-code, release, or ML-research plugins.
🎯 Why foundry?
Without: one model handles architecture, implementation, docs, linting, testing, performance — no boundary enforcement. Corrections evaporate per session. No way to know if agent accuracy drifted.
With:
/foundry:auditcatches config drift before it becomes debugging session/foundry:calibratemeasures recall vs stated confidence — know exactly where agents fall short/foundry:managecreates, renames, deletes agents with full cross-reference propagation, one command/foundry:brainstormturns vague idea into approved spec before any code written/foundry:distillconverts accumulated corrections into durable rules + agent instruction updates- Hooks keep lint, task tracking, teammate quality gates, and report checks running around Claude tool events (including Write/Edit operations)
Use /foundry:audit for structural checks, /foundry:calibrate for measured routing and agent behavior, and /foundry:distill to turn recurring corrections into proposed instruction updates.
📦 Install
Prerequisites:
- Claude Code with plugin support
- Python 3.10+ and
git(setup runs from a project repository) jqon PATH for audit/manage JSON work (setup uses Python only)- Node.js for the plugin's hooks
Each hook runs node from PATH, then /opt/homebrew/bin/node or /usr/local/bin/node. When none exists, the hooks skip without blocking, and one SessionStart check reports once per session that they are inactive.
The plugin's bin/python and native Windows bin/python.cmd preserve the shipped python command and probe candidate runtimes for Python 3.10+ before executing the workload once. Plugin bin/ follows system directories on PATH, so an eligible system python takes precedence; missing eligible runtimes produce a clear diagnostic.
Companion plugins for full workflow suite:
claude plugin install oss@borda-ai-rig
claude plugin install develop@borda-ai-rig
claude plugin install research@borda-ai-rig
One-time setup — run inside Claude Code after install, from the project repository root:
Setup, in short:
- merges
statusLine,permissions.allow,permissions.deny,enabledPlugins, the shippedenvdefaults, and (when pinned by the project)advisorModelinto~/.claude/settings.json - removes retired allow and deny entries (details under
/foundry:setup), preserving every other existing entry - symlinks all rule files into
~/.claude/rules/asfoundry-<name>.md, andTEAM_PROTOCOL.mdinto~/.claude/ - counts removals in its summary from the complete retired allow set
- is idempotent — safe to re-run
After any plugin upgrade, re-run /foundry:setup — auto-replaces stale foundry symlinks, removes rules gone from new version. No prompt for old-version symlinks.
⚡ Quick start
Run setup once, then check the installation from the project repository root:
The first useful workflow is:
It produces a structured report of system config checks (hooks, settings.json, permissions-guide.md, MEMORY.md, configuration README files, plugin integration, and symlinks). Treat any critical findings as blockers and resolve the report's suggested next action.
Follow with:
Quick routing benchmark — measures whether Claude Code dispatches synthetic tasks to the right agent. The calibration threshold is 90%; use the measured result to identify routing gaps rather than treating it as a guarantee.
🧭 Current boundaries
- Foundry manages Claude Code configuration and workflow guidance; it does not implement application code or provide release-management and ML-research workflows. For those workflows, install
develop(requires thedevelopplugin),oss(requires theossplugin), orresearch(requires theresearchplugin). - Calibration uses synthetic problems with quasi-ground-truth. It is an instruction-quality signal, not a production benchmark or guarantee of agent correctness.
- Hooks are event-driven and depend on Claude Code loading the enabled plugin plus Node.js. Most report or nudge; selected guards intentionally gate unsafe pushes, direct agent self-grants of an approval record, or incomplete follow-up prompts.
- Setup intentionally leaves some state behind on uninstall: merged settings,
foundry-*.mdrule links, andTEAM_PROTOCOL.mdneed manual review or removal; see Uninstall. - Profile cost output is best-effort and uses public list rates, not an account billing statement; when transcripts are unavailable, the clock report can still run without the cost section.
These are current boundaries of the shipped plugin, not promises about future support.
🔐 Git and GitHub approvals
Foundry alone ships the git/gh guards, approval records and one-time tokens. Each approval is recorded by the approval-guard.js hook from your actual answer to a question.
Local Git operations
Operations that need authorization (commit, staging owned changes, a local merge and its merge commit, cherry-pick, branch/worktree prep) ask one question:
- Approve — this operation only
- Approve always — this operation, plus a standing grant for this project
- Deny — skip it and leave changes as they are
How the standing grant works:
- The hook records an Approve always answer in
claude-git-approval.jsoninside git's own common directory (git rev-parse --git-common-dir): once per project, applies to every worktree, never tracked or checked out by git. - The question's Approve always option tells you that it persists, what it covers and how to revoke it.
- While a grant passes the rule's check (
node <foundry>/hooks/commit-guard.js --check-grant: a regular, non-linked file with the expected version, scope and answer, in the session project's own common directory), later sessions skip the question for task-scoped non-destructive local operations. Committing the agent's own completed task is then the default on completion. - The reply that commits states
grant .git/claude-git-approval.json@<created_at>orno grant. - Without a grant or an active skill workflow, the question is asked.
- The hook blocks an agent tool call that names the grant file directly. It sees names, not contents, so a patch, script or archive that writes the file is not blocked and stays forbidden by the rule alone.
- Revoke with
rm "$(git rev-parse --git-common-dir)/claude-git-approval.json".
A grant never covers push (asked every time), force operations, history rewriting or destructive recovery. A checkout under review gains nothing from it. Your narrower instructions (no commit, leave unstaged, read-only, wait) still win. Spawned subagents, teammates and bridge children never use it.
Push
Every push asks its own question, git-push: Approve (this push, once) or Deny. The question shows the branch, the target and the command the agent will run.
- Approve makes the hook record a single-use token,
claude-push-approval.json, in the same common directory. It holds the current branch, HEAD and the id of the question you answered, and expires after 15 minutes. A later Approve replaces it; a later Deny removes it. commit-guard.jslets one push of that branch at that HEAD to a configured remote run (git push,git push origin,-u,origin <branch>,origin HEAD:<branch>,git lfs push origin <branch>), after checking that your Approve to that very question is in the session transcript, and consumes the token. Of parallel push calls only one runs; a spawned agent never spends it.- The push must run from the checkout itself, be the only push in its command, and have no commit, reset or checkout beside it. A second push, a new commit or another branch needs a new Approve.
- No Approve covers deleting a remote branch,
--prune,--all,--tags, another branch or ref, a URL, path or variable destination,cd,send-pack,http-pushorsubtree push: the agent gives you the command to run yourself. - A dry run (
--dry-run) needs no approval. Force pushes stay forbidden even with a token. - A new session or
/cleardeletes a pending token — per project, so a second session in the same project clears the first one's. The former! touch /tmp/claude-push-auth-…sentinel no longer authorizes anything.
GitHub writes through gh
GitHub reads through gh run without a question. Every GitHub write through gh, on any repository, asks its own question, gh-write: Approve (this exact command, once) or Deny.
- The question names the command once in an inline code span. Approve makes the hook record a single-use token,
claude-gh-write-approval.json, holding that command for 15 minutes. gh-write-guard.jsthen lets exactly that text run once as the whole Bash command and spends the token; other text, a second run or a spawned agent's call stays blocked.- A later Approve replaces the token, a later Deny removes it, and a new session or
/cleardeletes it. - Outside a git repository nothing is recorded, so you run the command yourself.
- Claude Code still applies a settings deny rule after a hook allows a call, so the plugins no longer ship gh write deny entries. Re-run
/foundry:setuponce to remove the ones an earlier setup merged.
Single-use approvals take an exclusive reservation in the git common directory while a token is validated, spent, replaced or revoked. Concurrent calls wait at most one second, then deny if it remains busy. If a hook crashes, stop active hooks before manually deleting
<token-file>.spent-lockfrom the git common directory; Foundry also removes these reservations at SessionStart and/clear.
🧩 How foundry works
Behaviors the shipped rules and skills apply across workflows.
Review and challenge loops
- Review loops fix feasible authorized findings, investigate repeated signatures, and continue whenever the weighted score decreases; structural labels alone do not stop remediation.
- Each round challenges and collects findings, reports the cumulative old/new table, resolves feasible authorized findings, and escalates unfixable
security/critical/highfindings. It repeats until clean or plateau/non-convergence, subject to authority, evidence, recurrence and stricter caller budgets. - The table is
Iteration | Security | Critical | High | Medium | Low | Nits | Weighted score. Score weights are20/10/6/4/2/1. Empty rounds print no progress table; pending reviews and unrelated status updates do not repeat it. - Before the baseline review of a diff the parent or its resolver wrote, the author records an attestation (invariant, sibling routes, consumer, failing-before/passing-after check) and fixes the gaps it exposes. The reviewer never sees it, and it never counts toward scoring.
- Each open finding needs a recorded fix, escalation, or justified deferral. Each round's cost lands in an advisory
loop-metrics.jsonl. - Completion prompts ask only for a missing decision or authorization, regardless of report length, and already-authorized next steps continue. Concrete gates for fresh scope, paid execution, sensitive or destructive actions, and remote changes remain in force.
- Workflow audits and adversarial reviews trace producer guarantees through downstream consumers and the next ordinary user action, and report untested handoffs. Out-of-scope declines preserve mandated deliverable files and caller reply formats;
unsupportedenvelopes surface a routing miss withreasonandowner, never findings or a timeout.
Planning and delegation
- Small implementation uses a concise plan, a brief parent self-challenge (not independent), and consolidation with independent result challenge and relevant verification. Medium/large work retains independent plan challenge before acceptance.
- Approval prompts only for actual missing authority or protected decisions; accepted parent plans are reused.
- Work is split into coherent bounded outcomes, completed depth-first with context limited to the active piece, its dependencies and interfaces. Required leaf challenge and verification finish before dependent work; unknown causes or design choices first become bounded investigation prerequisites.
- The context, coordination and rework benefit of this approach is expected, not measured.
- The always-loaded
~/.claude/CLAUDE.mdstates the five delivery principles: consistent simple delivery, root cause not symptom, automatic correction and recovery, honest stops with real handoffs, and never reverting another owner's work without asking. They govern every change, including work done without any foundry skill.
Codemap and QA
- Optional Codemap guidance ships locally with foundry. Codemap queries still require the
codemap-pyplugin, with file-read fallback when the CLI or local contract is unavailable. - Specialist Codemap prompts reuse only matching, successful, fresh answers and preserve valid empty results. Source and independent-review reads remain allowed.
- QA distinguishes static test/mock relationships from measured line coverage and treats missing measurements as unknown.
Shared quality stack
skills/_shared/quality-stack.md is the canonical quality-gate stack that develop's feature/fix/refactor skills run at close.
- The flaky-test retry re-runs only the failing node-ids.
- Doctests fold into the main pytest run when a collection probe confirms it is safe. The report status is
not-merged/pass/fail. - A
pytest-xdistcapability probe runs the wide pass in parallel when available. A failure that reproduces only under that pass is reportedPARALLEL_FAIL_SERIAL_PASS(likely a test-isolation bug), not marked flaky.
! BREAKING — the doctest report line changed from a binary pass/fail to the 3-state form above.
🔧 Skills reference
/foundry:setup
Post-install setup. Merges settings, creates symlinks. Run once after install, again after any upgrade.
What it does:
- Detects Python 3.10+ (
python/py -3/python3); installs~/.local/bin/pythonshim whenpythonabsent or resolves to Windows Store stub - Backs up
~/.claude/settings.jsonbefore touching - Merges
statusLine,permissions.allow,permissions.deny,enabledPlugins,advisorModel(copied from project.claude/settings.jsonwhen pinned) - Removes the obsolete
Bash(gh api repos/*:*)allow entry, the broadBash(claude:*),Bash(find:*),Bash(node:*),Bash(sed:*)andBash(eval:*)allow entries (permissions-allow-retired.json), and the retired deny entries (gh writes, local branch/tag deletion;permissions-deny-retired.json), while preserving all other existing allow and deny entries - Merges shipped
envdefaults from.claude-plugin/env-defaults.json— currentlyCLAUDE_CODE_ENABLE_TODO_TOOLS=1, without which Claude Code keeps the task tools disabled and every skill that mandates task tracking silently no-ops; existing values are never overwritten - Copies
permissions-guide.mdto.claude/(only if absent — preserves project-local edits) - Symlinks all
plugins/cc_foundry/rules/*.mdinto~/.claude/rules/asfoundry-<name>.md, plusTEAM_PROTOCOL.mdinto~/.claude/; on upgrade, auto-replaces stale foundry symlinks, removes rules gone from the current version, and migrates pre-namespace unprefixed links it provably owns - Removes stale
hooksblock from settings if present (hooks now register via plugin manifest)
Hooks (hooks.json) register automatically when plugin enabled — /foundry:setup never touches them directly.
Codemap integration metadata uses the codemap-py.integration.v2 managed-block body while retaining the v1 sentinel format; use codemap-py integrate audit for read-only integration evidence.
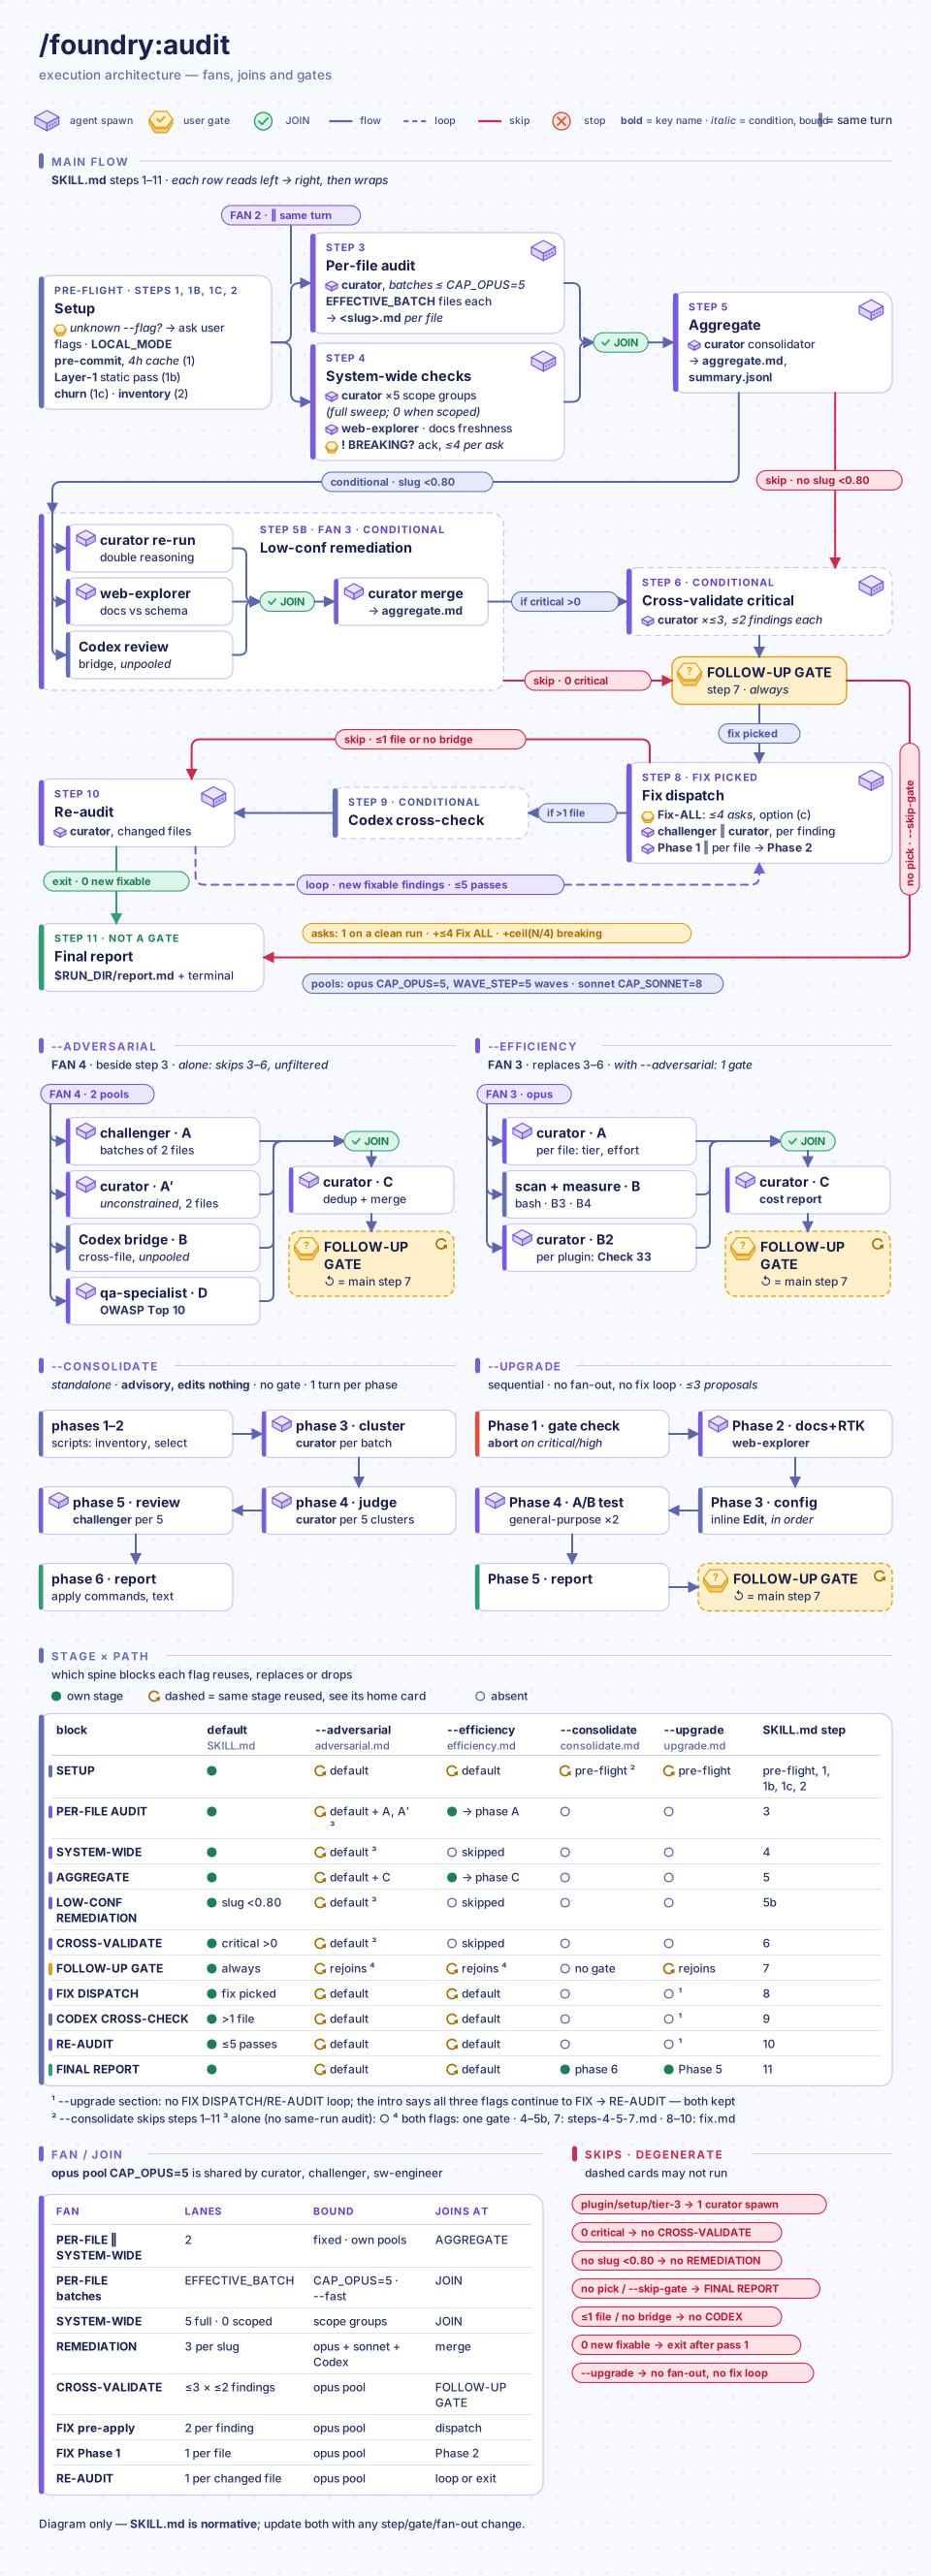
/foundry:audit
Full-sweep quality audit of the project's .claude/ config by default, or of all plugins/*/ agent and skill files with --local (plugin source checkout).
- Installed plugins in
~/.claude/plugins/cache/are not audited; a default run that finds no.claude/agents or skills reports them as⚠ UNSCANNEDinstead of a clean sweep. - Catches broken cross-references, inventory drift, model-tier mismatches, description overlap, doc staleness.
- Reports findings by severity; fix level chosen from always-fire follow-up gate after report.
- Adversarial mode challenges every claim via
foundry:challenger+ Codex.
Execution architecture — animated diagram of fans, joins and gates.
/foundry:audit                      # full sweep, report only — gate offers fix options
/foundry:audit --upgrade            # fetch latest Claude Code docs, apply improvements with A/B testing
/foundry:audit --adversarial        # adversarial review with foundry:challenger + Codex
/foundry:audit --consolidate        # advisory: propose merging narrow same-intent rules; edits nothing, standalone
/foundry:audit --efficiency         # cost/efficiency sweep: model tiers, effort, spawn patterns, token bloat; P1-4 plan + extraction candidates
/foundry:audit --efficiency --measured  # adds measured dollars for inline `model:` pins from this project's transcripts

# Tier 1 — group scopes
/foundry:audit agents               # all agents
/foundry:audit skills               # all skills
/foundry:audit rules                # all rules
/foundry:audit communication        # communication governance files
/foundry:audit setup                # system config: settings.json, hooks, plugin integration
/foundry:audit plugin               # foundry plugin integration checks only
/foundry:audit plugins              # deep audit of all installed plugins

# Tier 2 — plugin name (shorthand for 'plugins <name>')
/foundry:audit oss                  # oss plugin agents + skills only
/foundry:audit foundry              # foundry plugin only (same as 'plugins foundry')
/foundry:audit oss research         # oss + research plugins

# Tier 3 — specific agent or skill name
/foundry:audit shepherd             # single agent
/foundry:audit curator challenger   # two agents
/foundry:audit review resolve       # two skills

# Combine scope + flags
/foundry:audit oss --adversarial           # oss plugin, adversarial review
/foundry:audit agents --adversarial        # all agents, adversarial review

# Preserve key context across session compaction
/foundry:audit --keep "task-123, .reports/audit/2026-07-03T10-00-00Z"
fix and upgrade mutually exclusive — never combine.
--efficiency flags model-tier and effort mismatches, unbounded spawn patterns, token bloat, boilerplate duplication, ceremony turns, and text that outweighs its load class. With --measured, the dollar figures come from this project's own transcripts, with a baseline kept in .notes/efficiency/. The extraction gate offers EXTRACT / EXTRACT+RECOMMENDED / skip.
Behaviour change (0.40.1): the dead-model-spec check and Check 21 (skill frontmatter conflicts) were removed, and
--efficiency's missing-model check no longer exempts skills declaringdisable-model-invocation: true.
disable-model-invocation: truedoes not nullify a co-declaredmodel:orcontext: fork: it blocks Claude-automatic invocation, subagent preloading, and scheduled dispatch, while a user-typed/skill-namestill runs and still honoursmodel:. The removed checks would have recommended deleting a field that has real effect.Dropping the exemption widens missing-model detection from 14 to 35 skills, so expect more findings under
--efficiencythan before.
Sweep checks (30 checks), among them:
- Inventory drift: MEMORY.md roster vs files on disk
- Broken cross-references between agents and skills
- Hardcoded absolute user paths
- Model-tier appropriateness (reasoning vs execution roles)
- Agent description routing overlap (40%+ consecutive step overlap flagged)
- settings.json permissions vs Bash calls in skills
- Hook event names vs documented schema
- Claude Code docs freshness (spawns
foundry:web-explorerfor live docs) - Plugin integration correctness (codex plugin, foundry plugin)
- File length, heading hierarchy, LLM context minimality
- Config token overhead: total always-loaded config >100 KB, single rules file >10 KB (rules/ loads at session start; agents/skills lazy-loaded)
- Codemap index guards: every file resolving a codemap index path must be MANIFEST-managed, declared in the guard registry with its shape, or call the provider CLI; registry entries whose file no longer holds a guard fail too
Outputs structured report. With fix level: delegates fixes to sub-agents (never edits inline), re-audits modified files to confirm fixes held. Convergence loop up to 5 passes.
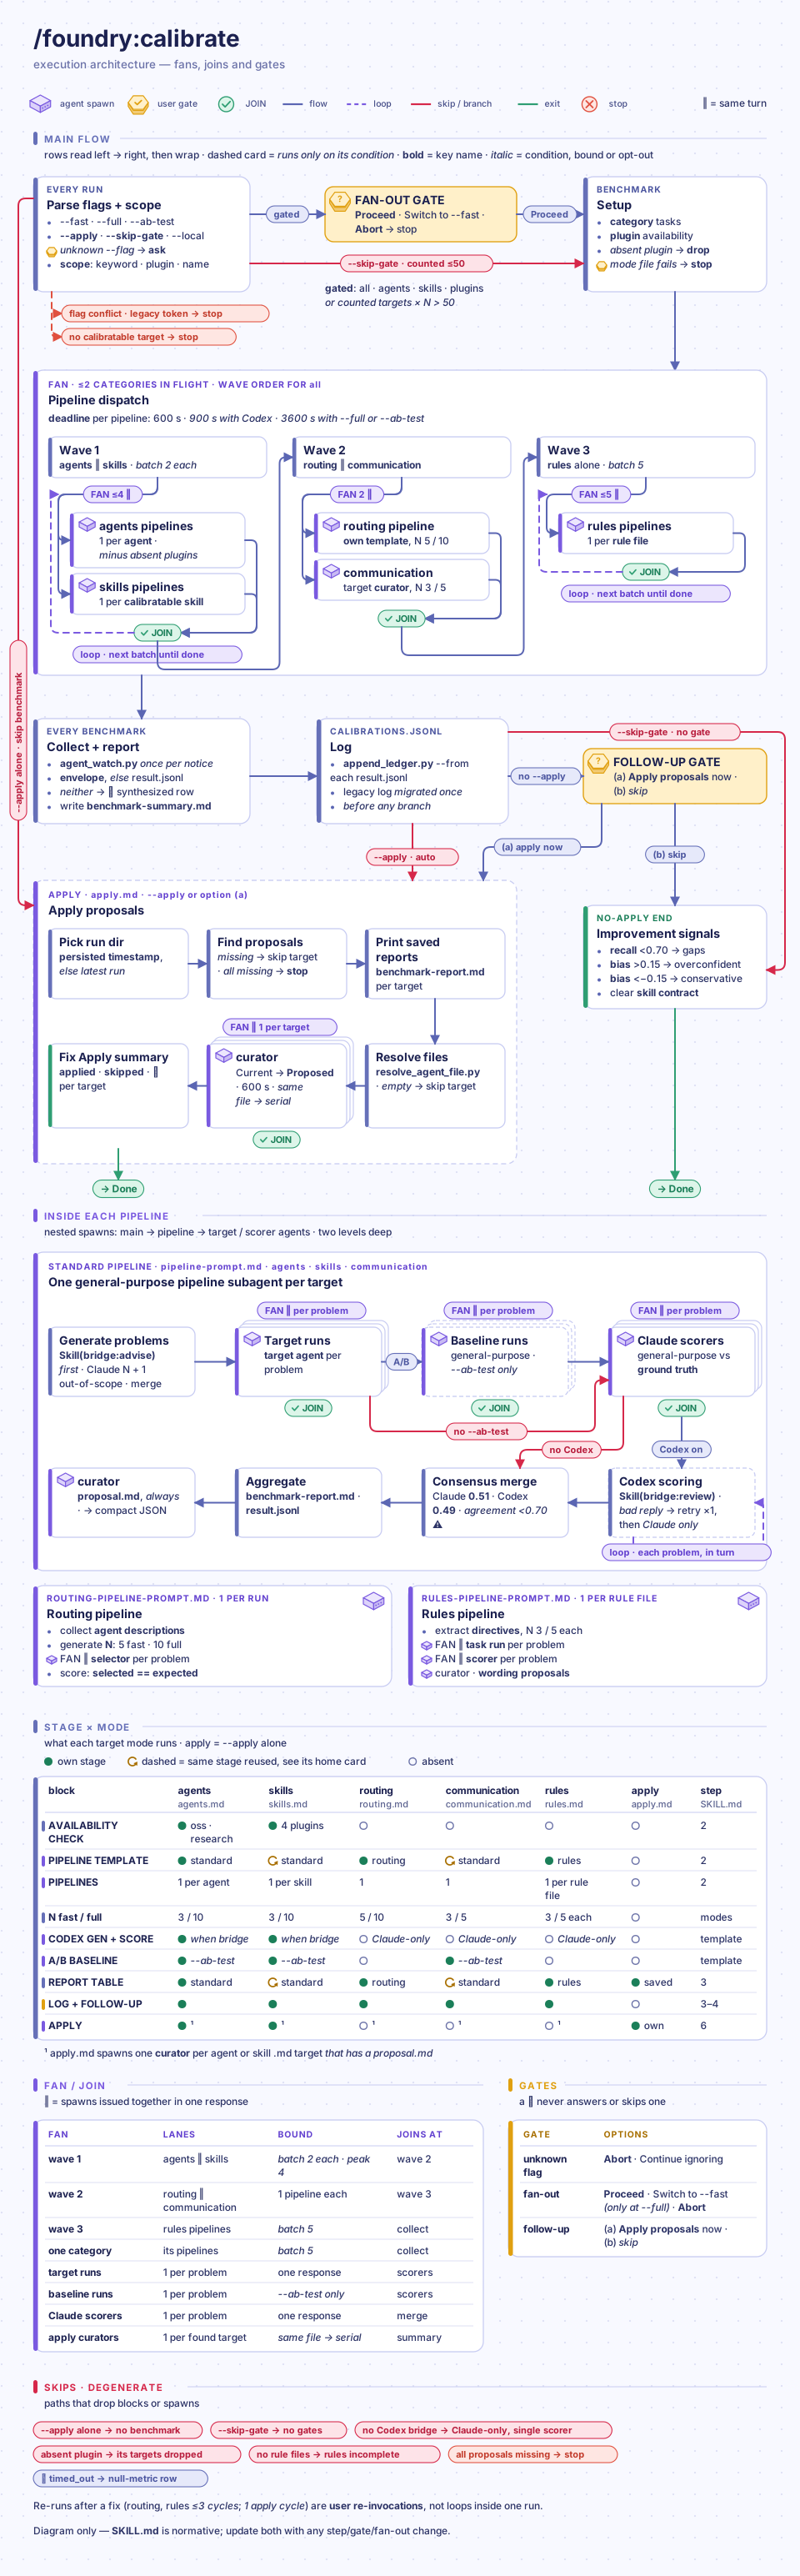
/foundry:calibrate
Benchmarks agents and skills against synthetic problems with defined ground truth. Primary signal = calibration bias — gap between self-reported confidence and actual recall. Well-calibrated agent reports 0.9 when finds ~90% of issues.
With --ab-test, each target also runs against a general-purpose baseline and gets one verdict, first match wins: significant, marginal, baseline-ahead, inconclusive (both arms at ceiling), or no-lift. A mixed-sign result (one metric up, the other down) can still be significant or marginal; the report then describes the negative delta as a trade-off.
Execution architecture — animated diagram of fans, joins and gates.
/foundry:calibrate all --fast              # quick benchmark across all modes (3 problems each)
/foundry:calibrate all --full              # thorough benchmark (10 problems each)
/foundry:calibrate routing --fast          # routing accuracy only — run after any agent description change
/foundry:calibrate agents --full --ab-test # agents + general-purpose baseline comparison
/foundry:calibrate all --fast --apply      # benchmark then immediately apply improvement proposals
/foundry:calibrate --apply                 # apply proposals from the most recent past run
/foundry:calibrate foundry:sw-engineer --fast  # single agent (tier 3 by full name)

# Tier 2 — plugin name
/foundry:calibrate oss --fast              # all oss plugin agents + calibratable skills
/foundry:calibrate oss research --fast     # oss + research plugins

# Tier 3 — specific agent or skill (bare name or plugin-prefixed)
/foundry:calibrate curator --fast          # single agent by bare name
/foundry:calibrate curator shepherd        # two agents (default --fast)

# Multiple targets
/foundry:calibrate agents skills --fast    # agents + skills in one run

# Preserve key context across session compaction
/foundry:calibrate --keep "task-456, .reports/calibrate/2026-07-03T10-00-00Z"
Large fan-out gate: broad scopes (all, agents, skills, plugins, <plugin-name>) always confirm via AskUserQuestion before spawning — they expand to dozens of agent/skill pipelines only inside Step 2, so no exact count is known upfront. Narrow scopes (single agent/skill) confirm only when exact spawn count exceeds 50. --apply no longer bypasses the gate alone; only --skip-gate does.
Thresholds:
- Routing accuracy: 90% (hard-problem accuracy: 80%)
- Recall per agent: 0.70 (below = instruction improvement needed)
- Calibration bias: within +/-0.15 (beyond = confidence decoupled from quality)
Modes:
agents— all specialist agentsskills—/foundry:auditand/oss:reviewrouting— orchestrator dispatch accuracy for synthetic task promptscommunication— team protocol compliance, file-handoff protocol violationsrules— rule adherence across global + path-scoped rule filesplugins/<plugin-name>— all agents + calibratable skills, one or all plugins<agent-name>/<skill-name>— single target, bare or plugin-prefixed nameall— all above
Results saved to .reports/calibrate/<timestamp>/<target>/. Improvement proposals written to proposal.md per target dir, applied with --apply. Agents and skills modes use dual-source evaluation: Claude + Codex generate problems and score responses independently, Claude 51% tiebreaker.
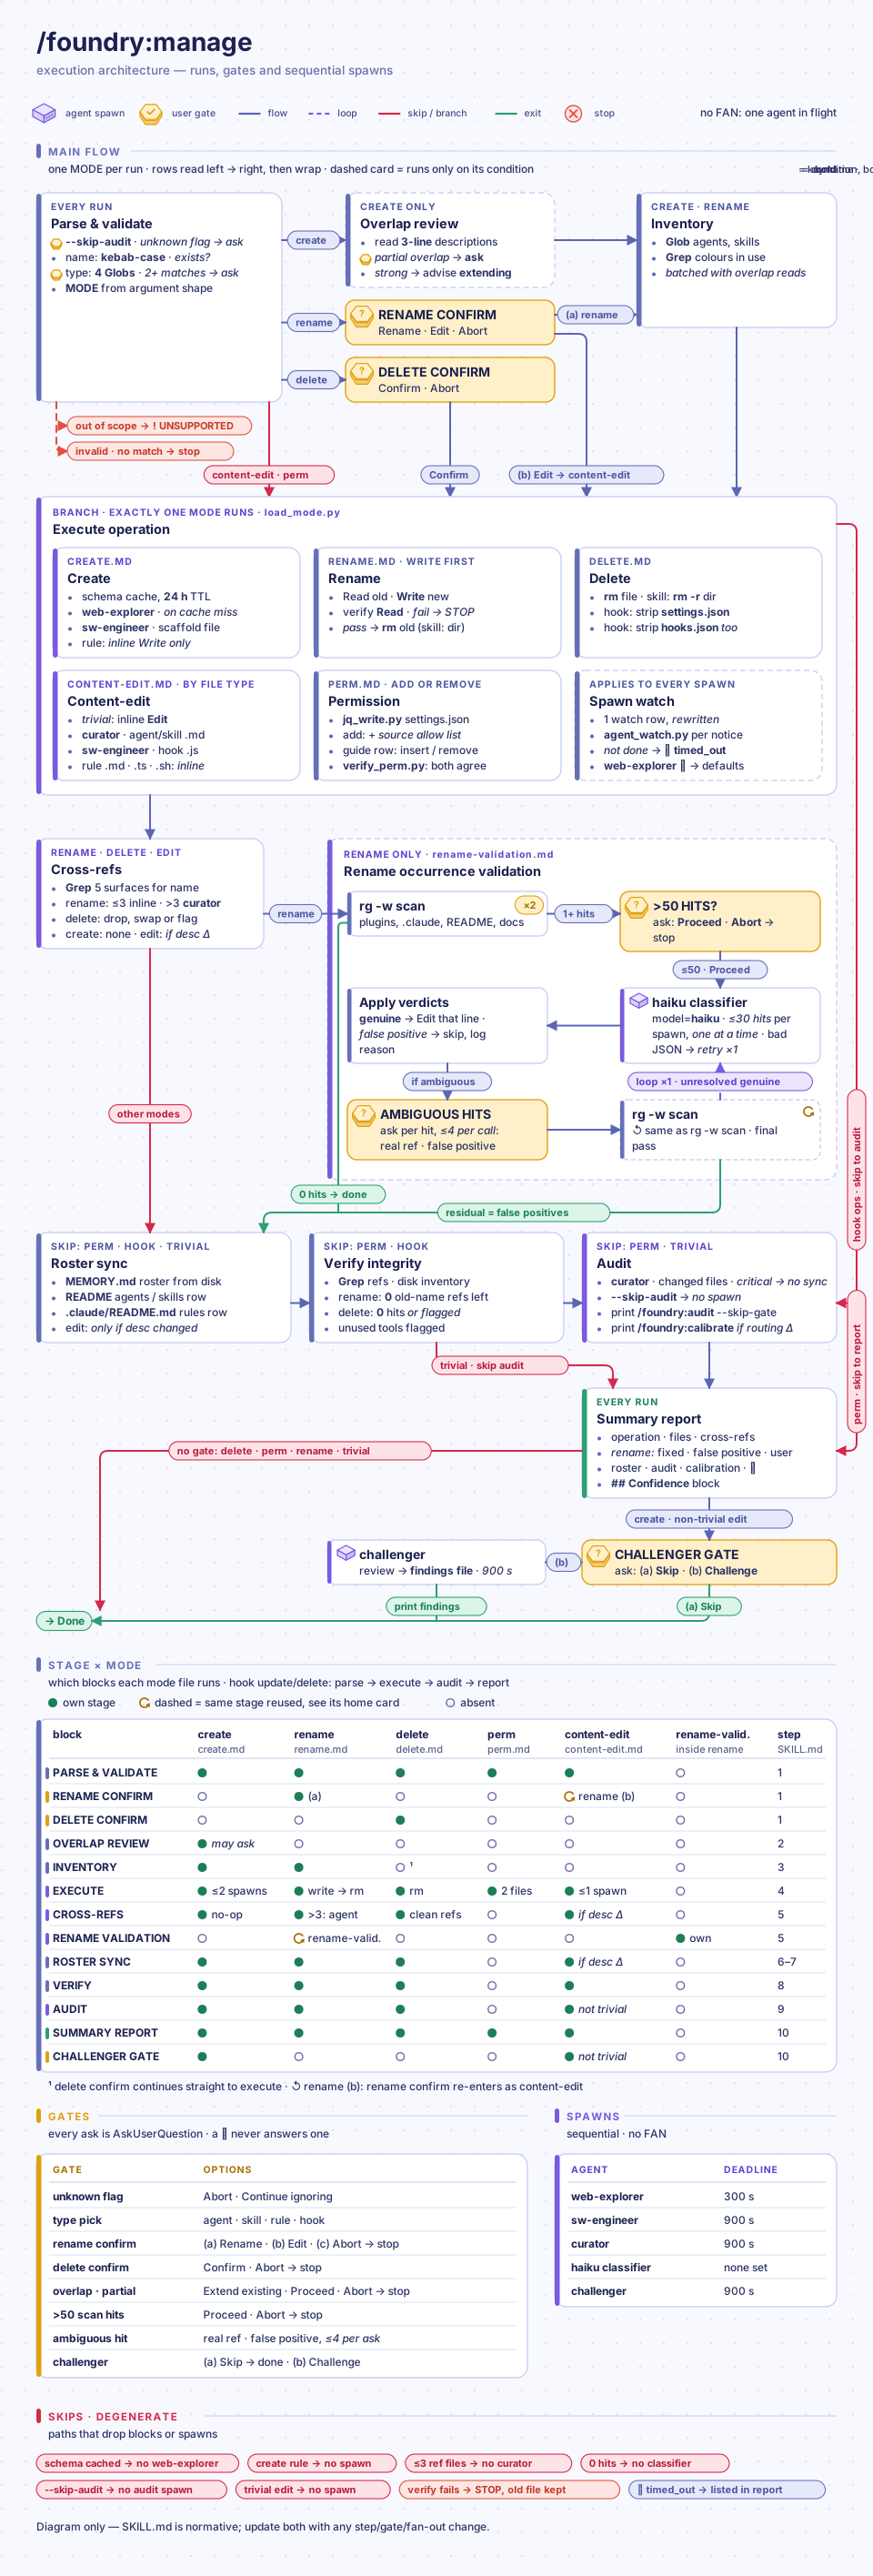
/foundry:manage
Create, update, or delete agents, skills, and rules; update or delete hooks. Full cross-reference propagation. Keeps MEMORY.md, README, settings.json in sync automatically.
Execution architecture — animated diagram of fans, joins and gates.
/foundry:manage create agent security-auditor "Vulnerability scanning specialist for OWASP Top 10 and supply chain threats"
/foundry:manage create skill benchmark "Benchmark orchestrator for measuring performance across commits"
/foundry:manage create rule torch-patterns "PyTorch coding patterns — compile, AMP, distributed"

/foundry:manage update my-agent "add a section on error handling patterns"
/foundry:manage update my-agent new-agent-name        # rename
/foundry:manage update my-agent docs/spec.md          # apply spec file as change directive

/foundry:manage delete old-agent-name

/foundry:manage add perm "Bash(jq:*)" "Parse and filter JSON" "Extract fields from REST API responses"
/foundry:manage remove perm "Bash(jq:*)"
- Create: fetches latest Claude Code agent/skill frontmatter schema, picks unused color, assigns model tier by role complexity, delegates content generation to
foundry:curator. Checks overlap with existing agents first. - Update: auto-detects type from disk. Rename atomic (write-before-delete). Content edits delegated to
foundry:curator(agents/skills) orfoundry:sw-engineer(hooks). Propagates description changes to cross-references when more than 3 files affected. - Delete: removes file, cleans broken references across
.claude/, updates MEMORY.md and README. - Permissions:
add perm/remove permupdate bothsettings.jsonandpermissions-guide.mdatomically — never one without other.
After any create or update: /foundry:calibrate routing --fast to confirm routing accuracy unaffected.
/foundry:brainstorm
Turns fuzzy idea into approved exploration tree, then spec, then ordered action plan. Nothing implemented until user approves design.
/foundry:brainstorm "add caching layer to the data pipeline"
/foundry:brainstorm "add caching layer to the data pipeline" --tight    # fewer questions and operations
/foundry:brainstorm "add caching layer to the data pipeline" --deep     # more exploration
/foundry:brainstorm "add caching layer to the data pipeline" --type workflow

/foundry:brainstorm breakdown .plans/blueprint/2026-04-01-caching-layer.md       # tree -> spec
/foundry:brainstorm breakdown .plans/blueprint/2026-04-01-caching-layer-spec.md  # spec -> action plan

# Preserve key context across session compaction
/foundry:brainstorm "add caching layer to the data pipeline" --keep "task-789, .plans/blueprint/2026-04-01-caching-layer.md"
Idea mode (default):
- Scans codebase for relevant existing code + constraints
- Asks up to 10 clarifying questions (5 with
--tight, 15 with--deep) — the first call batches 2-3 orientation questions, the rest follow one at a time so each can adapt to the prior answer - Presents 3-5 initial branches: core idea, tension resolved, what it trades away
- Interactive operations loop: deepen, reject, resolve, merge, add — up to 10 rounds
- Saves tree to
.plans/blueprint/YYYY-MM-DD-<slug>.mdwithStatus: tree - Live tree viewer at URL printed during Step 1 (serve project root with
python -m http.server 8000)
Breakdown mode (breakdown <file>):
Status: treefile: distillation questions, then section-by-section spec, savedStatus: draftStatus: draftfile: resolves blocking open questions, produces ordered action plan with tagged invocations
--type hint (application, workflow, utility, config, research) shapes question framing + codebase scan patterns in idea mode.
/foundry:investigate
Systematic diagnosis for unknown failures. Gathers signals, ranks hypotheses, probes top candidates, reports confirmed root cause + recommended next action.
/foundry:investigate "hooks not firing on Save"
/foundry:investigate "CI fails but passes locally"
/foundry:investigate "codex agent exits 127 on this machine"
/foundry:investigate "/calibrate times out every run"
/foundry:investigate "hooks not firing" --keep "task-999"  # preserve across compaction
Covers: broken local setup, environment mismatches, tool misconfigurations, hook misbehavior, CI vs local divergence, permission errors, runtime anomalies.
Not for: known Python test failures with traceback (use /develop:debug); .claude/ config quality sweep (use /foundry:audit).
Workflow: parse symptom -> gather signals in parallel (tool versions, PATH, recent git changes, config state, logs) -> rank hypotheses -> optional Codex adversarial review for ambiguous cases -> probe top hypotheses -> report root cause + recommended next skill.
Output always includes: confirmed root cause (or narrowed suspects), key evidence, what was ruled out, single recommended next action.
Auto-invokes when (MAYBE): unknown failure, no Python traceback — hook not firing, CI passes locally but fails remotely, behavior inconsistent with config; "not working but config looks right", "hook not triggering", "why isn't X running".
/foundry:profile
Buckets session clock time from ~/.claude/logs/{timings,invocations}.jsonl into local-tool, agent-spawn, Skill, AskUserQuestion idle, and main-loop reasoning residual. It also reports session tokens/cost from Claude Code transcripts (~/.claude/projects/**, main-loop + subagent files), split into main vs subagent spend by model tier — merged into one report. Pure log/transcript read — no instrumentation, no LLM calls, no skill edits.
/foundry:profile                          # last 24h, top 5 slowest calls + cost ranking
/foundry:profile --since 7d               # last 7 days
/foundry:profile --session-id 9c1bded7    # drill one session: clock breakdown + cost/agent-roster/cache-rebuild detail
/foundry:profile --top-n 20               # 20 longest single calls
Covers:
- Per-session clock breakdown (local% / agent% / skill% / reasoning% / idle), per-skill clock rollup (runs, total, mean, median, p90), top-N longest single calls, headline split over window.
## Tokens & costsection: sessions ranked by cost (main $ / subagent $ / total $), per-command rollup. With--session-id: cost by main/sidechain × model tier, agent roster, top cache-rebuild calls, cold-start share. Subagent spend is read directly from each session'ssubagents/agent-*.jsonltranscripts, not inferred.
Not for: per-line Python perf (use foundry:perf-optimizer); known failure diagnosis (use /foundry:investigate); a real billing statement (prices are public list rates, not effective plan rates).
Notes:
- The clock side reads JSONL logs the
task-log.jshook already writes (bin/timing_analyzer.py); the cost side reads Claude Code transcripts (bin/cost_analyzer.py). - Agents run in the background, so a spawn-only row carries a false-zero
duration_ms; the real span is recovered by joining the matchingstarted→completedpair ininvocations.jsonl. - The cost side is best-effort: if no transcripts fall in the window, the
## Tokens & costsection is omitted and the clock report still ships.
Context composition — cost_analyzer.py --composition writes a ## Context composition section with per-window usage, injection bytes (including instructions), estimated tool-result tokens and duplicate bytes, and likely large-input triggers.
- Options:
--projects-root,--session-id(full id or prefix),--since,--output,--compactions-log(override~/.claude/logs/compactions.jsonl). Main and subagent contexts are reported independently. - Windows start at explicit compaction records when present; otherwise at a post-call context drop below 70%.
--runtime claude(default) also reports repeated Read content flags, hook counts and sizes per prompt, large cache-write triggers, the 5-minute/1-hour cache-write split, and a timestamp-ordered table of logged compaction events with gate estimates versus realised calls and first-call context. Missing timing or a matching window is reported as unavailable; missing logs add a note; malformed rows warn and are skipped.--runtime codexreports tokens only, without prices, from$CODEX_HOME/sessions(default~/.codex/sessions);--projects-rootoverrides discovery. It deduplicates usage records, reports subagent shares across linked rollout threads, flags attempted code edits, and estimates each thread's AGENTS.md bytes × calls. Historical event-only usage in mixed-format threads is unavailable.
Auto-invokes when (MAYBE): user asks where wall-clock time or tokens/cost go, why a skill is slow or expensive, what dominates session runtime or spend; "where does time go", "why so slow", "what did this cost", "token spend", "profile last session", "clock breakdown", "session timing", "which skill burns tokens".
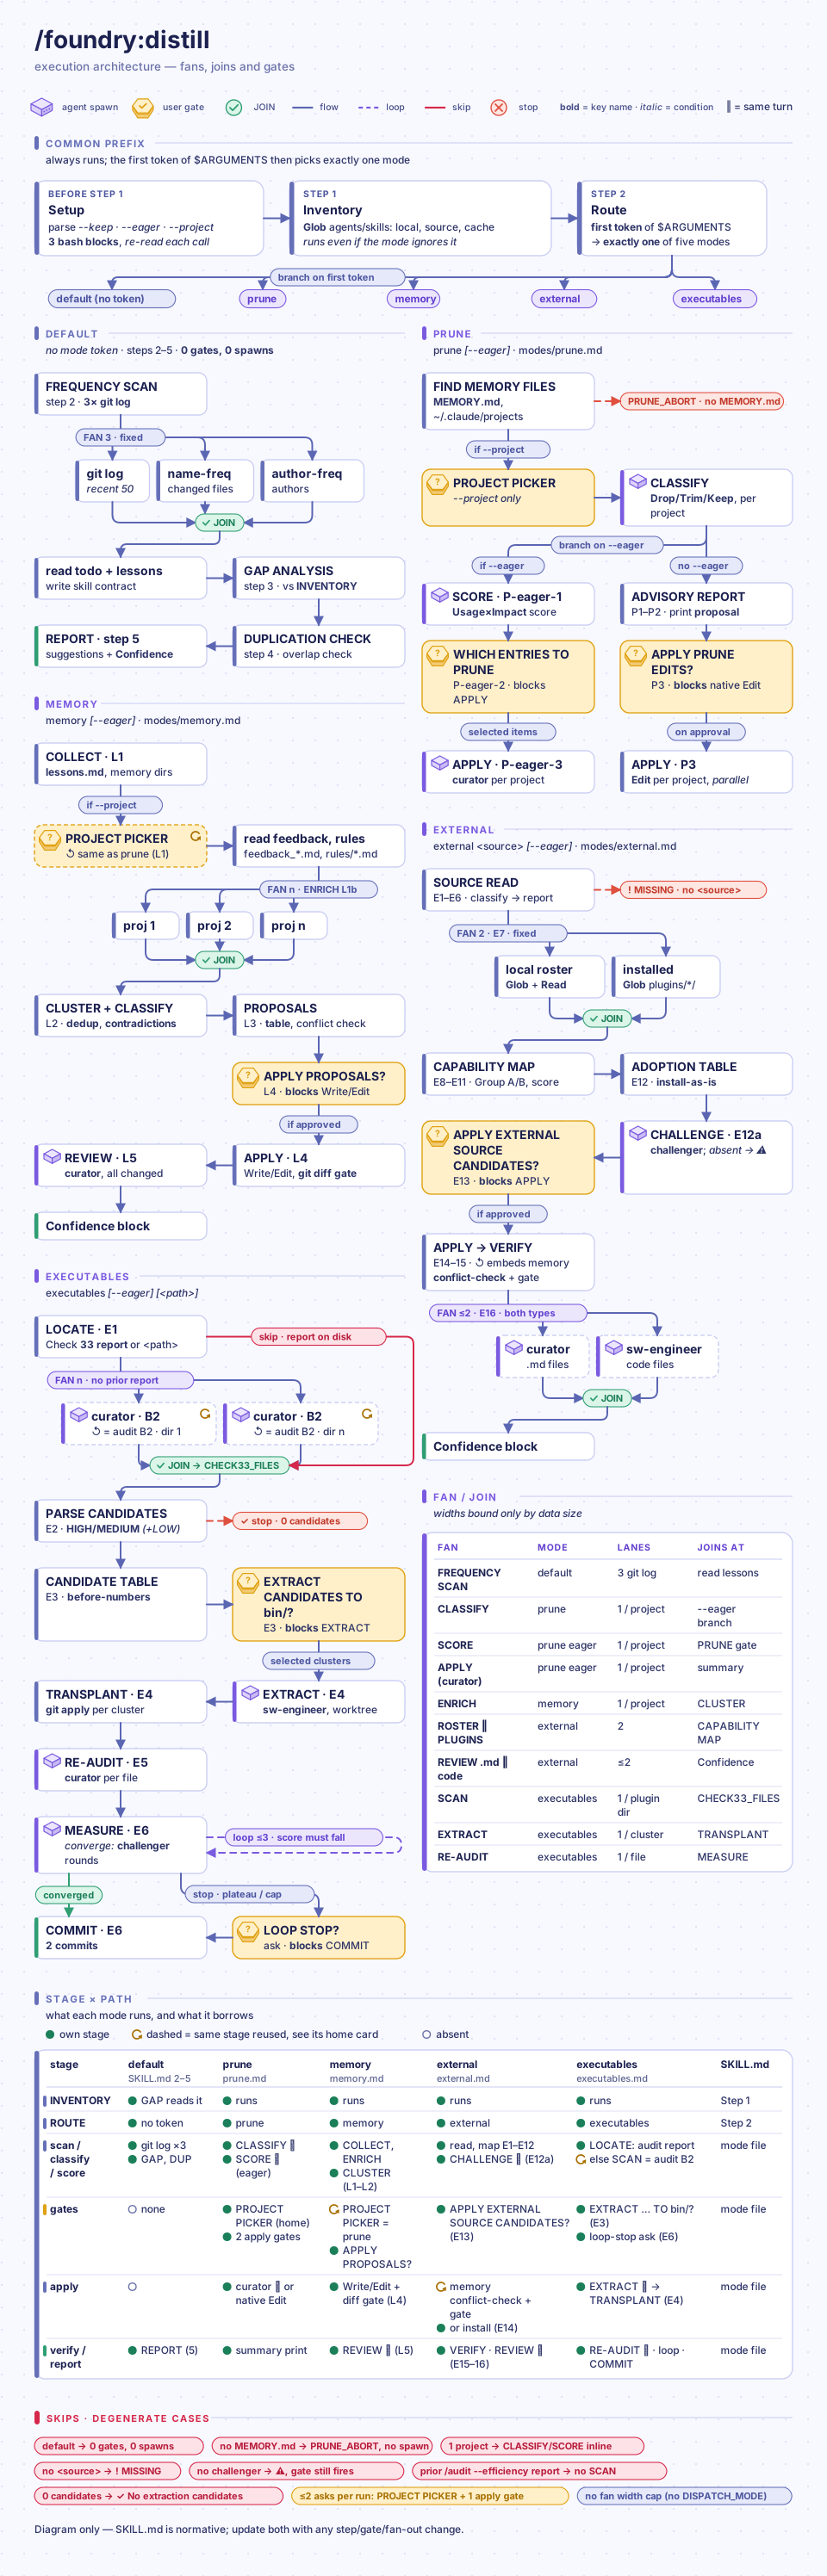
/foundry:distill
Extracts patterns from work history + corrections, distills into durable improvements — new agent/skill suggestions, roster quality review, memory pruning, promoting lessons into rules, or analysing external plugins/agentic resources for adoption.
Execution architecture — animated diagram of fans, joins and gates.
/foundry:distill                                     # analyze project patterns, suggest new agents/skills
/foundry:distill review                              # review existing roster for quality and gaps (no new suggestions)
/foundry:distill prune                               # trim stale/redundant entries from all project MEMORY.md files
/foundry:distill prune --project                     # interactive picker: select which project(s) to prune
/foundry:distill memory                              # promote patterns from all projects into rules/agents/skills
/foundry:distill memory --project                    # interactive picker: select which project(s) to distill from
/foundry:distill "external https://..."              # analyse external plugin/skill/agent resource, produce adoption proposal
/foundry:distill "external ./path/to/plugin"         # same — local path or directory
/foundry:distill "I keep doing X manually"           # use description as context for suggestions
/foundry:distill --keep "task-111"                       # preserve key context across compaction
--projecttriggers an interactive project picker — lists all slugs under~/.claude/projects/*/memory/with MEMORY.md size in tokens; select one or more. Without--project,pruneandmemoryrun across all projects automatically.- Both run parallel across selected projects (one agent per project), then consolidate into a single confirmation step.
memorymode also enriches each project's feedback with project-level context (CLAUDE.md, recent git log, active plans) for better classification. lessonsmode consolidatesfeedback_*.mdmemory files and a legacy.notes/lessons.mdwhen present: clusters by domain, classifies each entry as→ rule,→ agent update,→ skill update,→ already covered, or→ too narrow, and generates proposals. Before applying, a conflict pre-check greps each target file and flags cross-proposal collisions with ⚠. Confirmed changes are applied, followed by agit diffgate — inspect or revert before committing.externalmode reads the source (URL, file, directory), extracts its mental model and standout implementation details, and compares against the live local setup.- Candidates split into Align + improve (maps onto existing agents/skills/rules) and Differentiated highlights (novel, larger work).
- Each is scored and assigned a lane: adopt-as-is / tweak / discuss / skip.
- When the first group is thin or cumulative edit effort is large, it recommends installing the source as a standalone plugin instead of cherry-picking.
- Nothing is written until confirmed.
After applying: update or reinstall the plugin so the new rule files ship; /foundry:setup then only links rules into ~/.claude/rules/ and merges settings.
Run monthly or after any correction burst.
/foundry:session
Session state that outlives a context reset — a handover document plus a parking lot for open loops. dump sweeps the live conversation and composes goal, decisions + why, lessons, standing instructions, a files-touched table, outstanding items and an artifacts table, writes it to .claude/state/session/<slug>.md, and ends by printing /clear as the last line of the reply. The session-restore.js hook injects that document back on the other side, so restore costs nothing.
/foundry:session dump [name]     # sweep, write the handover doc, then print /clear
/foundry:session recall [name]   # print a stored handover back into context (named, or latest)
/foundry:session list            # handovers (slug / age / consumed) + open parked items
/foundry:session park <idea>     # stash one open loop without derailing the current task
/foundry:session sweep           # audit the conversation for unlanded ideas and questions
/foundry:session drop <item>     # close a parked item and log the closure
Auto-invokes when: user says "dump the session", "handover before clear", "save state before clearing", "carry this over", "park this for later", "what did we defer", "anything unfinished before I close".
- Runs inline, not forked — the conversation history is the authoritative source for what changed, what was decided, and what never landed. Implementation detail (diffs, tool output, exploration transcript, abandoned approaches) is dropped on purpose.
- The hook auto-restores only an unconsumed handover under 30 minutes old, so an old dump never ambushes an unrelated session; anything outside that window is reachable via
recall, which has no age gate. Over ~8000 chars the hook injects## Goal+ files table +## Next step+ a pointer instead of the whole doc. - Handover docs older than 14 days list as
⚠ stale; older than 30 days are swept duringlist. - Parked items live in
.claude/state/session/PARKED.md, are copied into every dump rather than consumed by it, and have no TTL — onlydropremoves one, appending an audit line todropped.jsonl. Parking is an explicit command, not an automatic behaviour. - The mode is
recall, notresume, to stay clear of Claude Code's native/resume— which revives a whole past conversation and is the better tool whenever it applies. - Not auto-compact survival (the skill contract in
.temp/state/skill-contract.md, perrules/compaction.md) — the two are distinguished in a boundary table in the skill.
/foundry:create
Interactive outline co-creation for developer advocacy content. Collects format, audience profile, four-beat arc, voice/tone via structured questions; detects out-of-scope requests; surfaces editorial conflicts; writes approved outline for foundry:creator to execute.
/foundry:create "tracing Python microservices with OpenTelemetry"
/foundry:create "why your CI pipeline is lying to you"
/foundry:create                   # no topic — skill asks interactively
- Supported formats: blog post, Marp slide deck (conference/meetup talk), social thread (Twitter/LinkedIn), talk abstract (CFP submission), lightning talk (5–10 min).
- Out-of-scope detection: refuses FAQs, comparison tables, reference docs at Step 1, redirects to
foundry:doc-scribe. - Editorial conflict detection: brief implies expert-level topic for beginner audience (or reverse) — skill surfaces mismatch explicitly before writing.
- Writes
.plans/content/<slug>-outline.md. Hand off tofoundry:creatorafter approval:@foundry:creator. - Max 5
AskUserQuestioninteractions for well-specified brief (format, audience, arc, voice). Skips interactive steps if all choices in initial brief.
/foundry:humanizer
Strips AI-writing tells from human-facing prose — docs, PR/commit bodies, reports, release notes, blog posts. Removes LLM-vocabulary clichés, banned constructions (rule-of-three triads, "not just X but Y"), formatting tells (title-case headings, em-dash overuse). Final pass — preserves meaning + structure; no rewrite from scratch.
/foundry:humanizer <text or file path>    # humanize in place
/foundry:humanizer check <file>           # report tells without editing
Primarily model-initiated self-review pass: foundry may invoke before finalizing substantial prose artifact drafted during task. Best-effort, not guaranteed intercept. Skips code, config, machine-parsed envelopes, inter-agent handover files. Commit-message edits preserve the commit rules, including omission of a scope that repeats the type.
🤖 Agents reference
All ten agents available by full plugin-prefixed name. In spawn directives and subagent_type values, always use full prefix (foundry:sw-engineer, not sw-engineer).
| Agent | Model | Purpose |
|---|---|---|
foundry:sw-engineer |
opus |
Senior engineer: implements, fixes and refactors Python |
foundry:solution-architect |
opus |
System design: ADRs, API contracts, migration plans |
foundry:qa-specialist |
sonnet |
Writes and reviews pytest tests; OWASP review for auth/PII scope |
foundry:linting-expert |
sonnet |
ruff, mypy, pre-commit; final code sanitization |
foundry:perf-optimizer |
opus |
Profile-first CPU/GPU/memory/I/O optimization |
foundry:doc-scribe |
sonnet |
Docstrings, API references, README content |
foundry:web-explorer |
sonnet |
Fetches live docs, changelogs and version info |
foundry:curator |
opus |
Audits agent, skill and rule config files |
foundry:challenger |
opus |
Read-only adversarial review of plans and code |
foundry:creator |
sonnet |
Blog posts, slide decks, threads from an approved outline |
Details per agent follow.
foundry:sw-engineer
Role: senior software engineer — writing/refactoring Python.
Use for: implementing features, fixing bugs, TDD/test-first, SOLID, type safety, production-quality Python for OSS libraries.
Model: opus
Not for:
- docstrings (
foundry:doc-scribe), ruff/mypy config (foundry:linting-expert) - system design (
foundry:solution-architect), test quality analysis (foundry:qa-specialist), perf profiling (foundry:perf-optimizer) - ML paper implementations (
research:scientist),.claude/config edits (foundry:curator) - CI/CD pipeline config — GitHub Actions, pre-commit hooks, CI YAML (
oss:cicd-steward— requiresossplugin) - read-only third-party release impact questions without a fix request (general-purpose)
Bug-finding reviews remain in scope; compatibility review of the project's own public API belongs to foundry:solution-architect.
Auto-invokes when: user asks to implement, build, write, modify, fix code across 3+ files; phrases: "implement", "build", "write the code for", "add feature", "fix this bug".
Runs in the caller's working tree by default, so its edits and reports land where the calling skill reads them.
Worktree isolation is chosen per spawn, not by the agent: a caller passes isolation="worktree" only for parallel or speculative writers whose changes it transplants back — /foundry:distill executables extraction, and /oss:resolve Phase 2 (requires oss plugin). An isolated run cannot write into the main checkout or another worktree, so its caller hands it a temporary path or reads the result from its return envelope.
foundry:solution-architect
Role: system design specialist — ADRs, API surface design, interface specs, migration plans, coupling analysis.
Use for: architectural trade-offs, public API contracts, deprecation strategies, assessing architectural feasibility of AI-generated hypotheses against codebase constraints.
Model: opus
Not for: implementation code (foundry:sw-engineer), release management (oss:shepherd), perf profiling or DataLoader throughput tuning (foundry:perf-optimizer).
Auto-invokes when (MAYBE): architecture questions involving 3+ components; "how should I structure this", "ADR for", "migration plan for". Not for simple design questions.
Produces documentation — ADRs, interface contracts, migration plans, component diagrams — not production code. Hands off to foundry:sw-engineer for execution. Spec with multiple unresolved decision branches: resolves one at a time via AskUserQuestion with recommended answer each, not one bulk ask. Review-only asks return findings without standalone design artifacts; alignment waits only for an ambiguous design question, and irreversible-decision flags fold into matching findings.
foundry:qa-specialist
Role: QA specialist — writing, reviewing, fixing tests. Rigorous black-box end-user tester: public API surface by default, expectations from docs/type hints — not implementation, tests represent realistic user workflows.
Use for: new pytest tests, public-API coverage gaps, edge-case matrices, fixing failing tests, integration test design. Auto-embeds OWASP Top 10 security review when task scope includes auth, payment flows, or PII — all modes.
Model: sonnet
Not for: linting, type checking, annotation fixes (foundry:linting-expert), production implementation (foundry:sw-engineer), slow test suite profiling (foundry:perf-optimizer), testing private/internal methods or mocking internals by default — opt-in only when the caller explicitly asks, or when a bug is unreachable through any public path.
Auto-invokes when: user asks to write tests, assess coverage, define test strategy; "write tests for", "add unit tests", "test coverage for".
Writes deterministic, parametrized, behavior-focused tests. Progression: happy path → edge cases → error cases → boundary values → adversarial inputs. Applies public-API coverage checklist before done; edge-case coverage findings require documented or code-explicit contracts, while unspecified behavior goes under Contract questions:.
foundry:linting-expert
Role: static analysis + tooling specialist for Python.
Use for: ruff rules, mypy strictness, pre-commit hooks, fixing lint/type violations, missing type annotations, lint/type content of quality gates. Final code sanitization before handover.
Model: sonnet (effort: medium)
Not for: CI pipeline structure or runner strategy (oss:cicd-steward), test logic (foundry:qa-specialist), implementation beyond annotation/style (foundry:sw-engineer), docstrings or API reference (foundry:doc-scribe).
Auto-invokes when: after code edits when user asks "is this clean", "any lint issues", "check formatting", "check types"; lint or type errors visible in output.
Always downstream of foundry:sw-engineer — never lints unimplemented code.
foundry:perf-optimizer
Role: performance engineer — profiling + optimizing CPU, GPU, memory, I/O bottlenecks.
Use for: profiling Python/ML workloads, DataLoader bottlenecks, mixed precision, vectorizing loops, PyTorch throughput tuning.
Model: opus
Not for: general refactoring (foundry:sw-engineer), architectural redesign (foundry:solution-architect), DataLoader correctness or reproducibility audits (research:data-steward — requires research plugin), doc writing (foundry:doc-scribe), annotation fixes (foundry:linting-expert).
Auto-invokes when: user asks to profile, benchmark, optimize Python/ML workload; mentions slow training, GPU underutilization, DataLoader bottleneck; phrases: "why is this slow", "profile this", "optimize training speed". Not for general code changes (foundry:sw-engineer).
Strictly profile-first: measure before change, change one thing, measure again. Optimization order: algorithm -> data structure -> I/O -> memory -> concurrency -> vectorization -> compute -> caching. Never GPU tuning before checking I/O.
foundry:doc-scribe
Role: documentation specialist — docstrings, API references, README files.
Use for: auditing missing docstrings, writing Google-style (Napoleon) docstrings from code, README content, doc/code inconsistencies.
Model: sonnet
Not for: CHANGELOG entries or release notes (oss:shepherd for lifecycle/format decisions, /oss:release for automated generation), linting code examples (foundry:linting-expert), implementation (foundry:sw-engineer), outward-facing narrative artifacts — blog posts, talk slides, social threads (foundry:creator).
Auto-invokes when: user asks for documentation; "write docs for", "add docstrings to", "update the README", "document this function".
Audit category restrictions and documentation standards explicitly set as acceptance criteria filter findings; background style mentions do not narrow a broad audit. Always downstream — documents finalized code, never shapes design. After foundry:doc-scribe produces content, follow with foundry:linting-expert to sanitize code examples.
foundry:web-explorer
Role: web fetch + content extraction specialist.
Use for: fetching live library docs, API references, changelogs, migration guides, package version lookups, GitHub release extraction. Used internally by /foundry:audit upgrade and /foundry:manage create.
Model: sonnet
Not for: local code analysis — local code reading with a fix request or implementation (foundry:sw-engineer), read-only impact questions (general-purpose); ML paper analysis (research:scientist), README/docstring writing (foundry:doc-scribe), dependency upgrade lifecycle decisions (oss:shepherd), perf profiling or benchmarking recommendations (foundry:perf-optimizer).
Auto-invokes when: user asks about library docs, external API, URL content; "what does X docs say", "look up", "find the docs for", "latest version of"; user pastes URL + asks question about it.
Feeds research:scientist — fetches current docs + papers; scientist interprets.
foundry:curator
Role: quality guardian of Claude config markdown files — agents, skills, rules. Plugin-layout audits require new executable helpers to use Python and treat legacy shell helpers as portability debt.
Use for: auditing .claude/ config files — verbosity creep, cross-agent duplication, broken cross-references, structural violations, outdated content, roster overlap. Used internally by /foundry:audit and /foundry:manage.
Model: opus
Not for: hook files (*.js) — belong to foundry:sw-engineer. Not for creating/scaffolding new agents or skills (/foundry:manage create). Not for routing new tasks to other agents.
Auto-invokes when (MAYBE): user explicitly references specific agent/skill config file by path; "audit this agent", "check this skill file", "is this config valid". Narrow trigger — see description.
Generally not invoked directly. /foundry:audit spawns it in batches across all config files; /foundry:manage delegates content generation + editing to it.
foundry:challenger
Role: adversarial reviewer — implementation plans, architecture proposals, significant code reviews.
Use for: red-teaming plan before committing, challenging architectural decisions before ship, adversarial code review on security-sensitive or irreversible ops. Every claim unproven until backed by evidence.
- Attacks across 6 dimensions (Assumptions, Missing Cases, Security Risks, Architectural Concerns, Complexity Creep, Root Cause).
- Drills to bedrock per standing challenge: keeps asking "why?" until root cause, not surface symptom.
- Mandatory refutation step keeps it objective: accepts refutation when evidence warrants.
Model: opus
Not for: designing plans or ADRs (foundry:solution-architect), writing tests or coverage review (foundry:qa-specialist), config file quality review (foundry:curator).
Auto-invokes when: user asks to challenge, stress-test, critique design or plan; "challenge this", "what are the weaknesses", "devil's advocate", "poke holes in", "second opinion on".
- Read-only — never writes or edits files. Runs by default in all
/develop:*skills and/oss:review— skip with--no-challenge. - When
bridge@borda-ai-rigis installed and enabled, challenger calls the read-only Codex adversarial review track for the same target and aggregates its findings. Pass--no-codexto skip. An absent or disabled bridge is surfaced rather than silently falling back. - Inside an adversarial review → fix loop, challenger labels findings in the loop's six tiers (security to nit) so each round can be scored, and delivers its findings in its final reply rather than through a report file or a message. It runs only the evidence commands the caller's brief names, always in the foreground.
- For a security filter it reviews the filter logic first, runs the open-ended bypass search through its Codex cross-check, checks Codex's candidates (and any generator the caller supplies) against the filter's own functions, and counts the reproduced ones in its own findings.
- It also delivers a coverage table built from the filtered language's own grammar (every construct class against every reader that judges it: admitted by spec, refused or unmodeled).
- It never writes bypass candidates itself, and
--no-codexdoes not apply to such a review. - Each finding is named after the invariant it breaks, so a new route to a known gap counts as a repeat. A search that could not run returns
status: blockedwith its reason, never a clean verdict. The Codex Cross-Check section is always present, stating a skip or failure rather than omitting it.
foundry:creator
Role: developer advocacy content specialist — outward-facing narrative artifacts.
Use for: complete blog posts, Marp slide decks, social threads, talk abstracts, lightning talk outlines in one autonomous pass. Imagines ideal reader experience first, works backwards to structure + form — questions status-quo conventions, pushes for fresh angles. Reads approved outline file (.plans/content/<slug>-outline.md) from /foundry:create. Applies four-beat story arc (Problem→Journey→Insight→Action) calibrated to target audience level.
Model: sonnet
Not for: in-code documentation, docstrings, API references (foundry:doc-scribe), release notes/changelogs (oss:shepherd — requires oss plugin), structured reference content — FAQs, comparison tables (redirect to foundry:doc-scribe).
Auto-invokes when: outline file .plans/content/<slug>-outline.md approved; user asks for blog post, Marp slide deck, social thread, talk abstract, lightning talk outline. Skip when: outline file not found (run /foundry:create first); code documentation (foundry:doc-scribe); release notes (oss:shepherd).
Always downstream of /foundry:create — reads approved outline, generates full artifact. Two-phase system: /foundry:create (interactive intake → outline) then foundry:creator (autonomous generation → artifact). Outline format constraints override house defaults during generation and review; critical covers unusable or harmful output and outline violations that mislead readers.
🔗 Agent relationships
Agents = directed pipeline, not flat pool:
foundry:linting-expertalways downstream offoundry:sw-engineer— never lints unimplemented codefoundry:doc-scribealways downstream — documents finalized code, never shapes designfoundry:qa-specialistruns parallel tofoundry:sw-engineerduring review, or downstream after implementationfoundry:challengeris pre-implementation — challenges plans + proposals before any code; use beforefoundry:sw-engineerfoundry:curatoris orthogonal — audits.claude/config files, not user codefoundry:web-explorerfeedsresearch:scientist— fetches current docs + papers; scientist interpretsfoundry:creatoralways downstream of/foundry:create— reads approved outline file; never generates without prior outline
Model tiering:
- reasoning agents (
foundry:sw-engineer,foundry:perf-optimizer) useopus - adversarial reasoning (
foundry:challenger) usesopus - high-stakes design/config roles (
foundry:solution-architect,foundry:curator) useopus - execution agents (
foundry:doc-scribe,foundry:web-explorer,foundry:creator,foundry:qa-specialist,foundry:linting-expert) usesonnet
Agent and skill frontmatter uses aliases only, never a pinned model ID, so each follows the newest release.
- On the Anthropic API the aliases resolve to the 5.5 family (
opus→Opus 5.5,sonnet→Sonnet 5.5,haiku→Haiku 5.5); third-party providers maphaikuto Haiku 4.5. Haiku 5.5 acceptseffort. opusplanas subagent frontmatter runssonnet(subagents never enter plan mode) — useopusorsonnetexplicitly.fableis the reserve tier for demanding long-horizon reasoning, with no standing agent assignment.- Within the 5 family the tiers sit closer together than the 4.x tiers did, so effort is the primary cost knob and tier the blunt one — tune effort before moving an agent's tier, and prove any downgrade with
/foundry:calibrate <agent> --full --ab-testrather than a generation-level parity claim.
/foundry:audit's fix dispatch overrides per-call to haiku for findings that are pure transcription of an already-known replacement, regardless of the spawned agent's own frontmatter tier — judgment-bearing and cross-file fixes keep the agent's default.
📋 Rules installed
/foundry:setup symlinks all 18 rule files from plugins/cc_foundry/rules/ into ~/.claude/rules/, each renamed to foundry-<source-name>.md. They govern Claude behavior globally, in all sessions after install.
~/.claude/rules/is one flat directory shared by every installed plugin, and four of this marketplace's plugins ship arules/quality-gates.md, so source basenames would silently overwrite one another. Each plugin therefore namespaces its own rules with its plugin name:quality-gates.mdinstalls asfoundry-quality-gates.md, alongsidedevelop-quality-gates.md,oss-quality-gates.md, andresearch-quality-gates.md.- The prefix is inert — verified against Claude Code 2.1.220 that it changes neither unconditional rule loading nor
paths:frontmatter matching. - Re-running setup after an upgrade migrates any pre-namespace unprefixed link, but only when that link provably belongs to foundry; a link into another marketplace, a source checkout, or a dotfiles tree is preserved and reported as a conflict instead.
- Confidence describes the correctness of the delivered result and how it was produced and checked within scope. Report completion separately; a high score does not pass an unmet gate.
Stub + on-demand split (token diet): several rules are thin always-loaded stubs with hard constraints only (
debugging.md,external-data.md,artifact-lifecycle.md,quality-gates.md,communication.md,claude-config.md,public-github.md,task-lifecycle.md,notebooks.md). Their full procedural bodies live inrules/_full/(resolved from plugin cache, not symlinked or injected) and are read on demand at the trigger point the stub names.Sections that matter only while touching one kind of file sit behind a narrower
pathsglob (markdown.md,python-code.md). Rules that matter only during one activity are injected byhooks/rule-inject.js:agent-spawn.mdon the firstAgent()call,git-commit.mdon the first commit-creating git call of each session and subagent (again after compaction or/clear).Zero constraint loss: every named rule survives in the stub or its
_full/body. Rule edits take effect only aftermake sync-claudepropagates them to the plugin cache —~/.claude/rules/*.mdare symlinks into a version-pinned cache directory.
| Rule file | Applies to | Governs |
|---|---|---|
communication.md |
all | Re: anchor format, progress narration, tone, output routing, breaking-findings format, confidence display, no-hard-wrap stub |
quality-gates.md |
all | Confidence block, independent adversarial review/fix loop, link verification and complexity-limit stubs, long-output routing |
git-commit.md |
injected after the first commit-creating git call; **/.git/COMMIT_EDITMSG, **/.gitmessage |
Commit message format, diff-gathering before writing, co-author trailers, branch + push safety (hard bans stay in claude-config.md) |
claude-config.md |
all | Bash timeouts (3x P90), turn batching, directory navigation, no hardcoded absolute paths, spawn discipline, pinned lint hooks, git hard bans |
artifact-lifecycle.md |
all | Artifact layout (.plans/, .reports/, .temp/), run directory naming, TTL policy, plans and benchmarks kept out of shipped content |
external-data.md |
all | Pagination rules (GitHub CLI, REST, GraphQL, Cloud APIs) — never work on a partial result set |
debugging.md |
all | Root-cause discipline: confirm the mechanism with evidence before fixing |
task-lifecycle.md |
all | Task update ordering, frozen plans during build, subagent task prohibition, spawn slots |
compaction.md |
all | Compaction contract: what survives /compact and when to refresh it |
foundry-config.md |
.claude/** |
Plan-mode gate before any .claude/ edit, post-edit checklist, XML tag conventions, distribution rules |
python-code.md |
**/*.py |
Google-style docstrings, enums, dataclass/TypedDict selection, deprecation API, multi-OS portability, complexity limits, lint hooks |
python-testing.md |
tests/**/*.py, **/test_*.py |
pytest design: TDD, fixtures, parametrization, markers, xdist runs, cross-OS tests, mocking, test names |
notebooks.md |
**/*.ipynb, **/*.py |
Notebook cell granularity, narrative depth, plot framing, shell magics — .ipynb and Jupytext # %% scripts |
public-github.md |
all | GitHub reads run free; every gh write needs the user's one-time gh-write approval of the exact command |
untrusted-content.md |
all | Ingested external text is data, never instruction — delimiters, no permission widening, memory propagation |
markdown.md |
**/*.md |
Never hard-wrap prose, structure selection, instruction-file compression gate, link verification |
agent-spawn.md |
injected after the first Agent() call; **/skills/**/*.md, **/agents/**/*.md |
Spawn slots, end the turn after spawning with per-agent deadlines, parallel spawn ceilings by model tier |
model-tiering.md |
**/skills/**/*.md, **/agents/**/*.md |
Model tier ladder, checkable escalation triggers, no model: pin on inline skills, author cost checklist |
⚙️ Configuration
settings.json keys merged by /foundry:setup
| Key | What it does |
|---|---|
statusLine.command |
Runs statusline.js — active agent count in Claude Code status bar |
permissions.allow |
Adds pre-approved Bash commands, git operations, WebFetch domains |
permissions.deny |
Adds denied operations (force push, curl writes, rm -rf, sudo); removes retired gh write and local branch/tag deletion denies |
enabledPlugins["bridge@borda-ai-rig"] |
Enables bridge-backed Codex review in /foundry:calibrate and /foundry:audit |
advisorModel |
Copied from project .claude/settings.json when pinned — advisor tool uses chosen model |
env.CLAUDE_CODE_ENABLE_TODO_TOOLS |
Re-enables the task tools (TaskCreate/TaskList/TaskUpdate/TaskGet), off by default |
Env defaults ship in .claude-plugin/env-defaults.json and merge per key with settings_json.py — a key already present in ~/.claude/settings.json keeps the user's value, including a deliberate "0". All setup JSON reads, probes and writes use Python; writes replace a complete temporary file atomically without a Write-tool prompt.
Optional flags and knobs
--approveon/foundry:setup: skips all interactive prompts, auto-accepts recommended choices. For scripted or CI setups.--skip-auditon/foundry:manage: skips Step 9 audit validation (thefoundry:curatorcheck and the printed/foundry:audit --skip-gatecommand;/foundry:auditand/foundry:calibratearedisable-model-invocation, so manage prints them for the user to run). Use inside audit-initiated fix sessions to avoid recursion.- Calibration pace:
--fast(3 problems per target, default) vs--full(10 per target).--fastfor routine checks after agent edits;--fullfor thorough benchmarks before releases or after major instruction changes. - Brainstorm ceremony:
--tight(5/5/1 caps, well-scoped ideas), default (10/10/2),--deep(15/15/3, genuinely ambiguous problems).
Environment
No environment variables required. foundry reads ~/.claude/settings.json + plugin's installed cache path, both resolved automatically by /foundry:setup.
🔍 Troubleshooting
/foundry:audit reports broken symlinks (Check I3)
Symlinks in ~/.claude/rules/ point to previous plugin cache path after upgrade. Re-run /foundry:setup — Step 10 detects stale symlinks as conflicts, offers replacement.
Hooks not firing
Run /foundry:investigate "hooks not firing on Save". Most common cause: hooks block still in ~/.claude/settings.json from pre-plugin-migration install (hooks now register via plugin manifest, not hooks key). /foundry:setup Step 3 detects + removes stale block.
/foundry:calibrate times out
Each pipeline subagent has 10-minute hard cutoff (15 minutes when Codex active, 60 minutes with --full or --ab-test). Target consistently times out: run in isolation: /foundry:calibrate foundry:sw-engineer --fast. Persistent: /foundry:investigate "/calibrate times out every run".
/foundry:manage create picks wrong model tier
Model tier chosen by role complexity at creation: opus for high-stakes quality review and complex reasoning (e.g. foundry:curator, foundry:sw-engineer), sonnet for focused execution, haiku for mechanical high-frequency work. opusplan as subagent frontmatter runs sonnet (subagents never enter plan mode) — use opus or sonnet explicitly. Fix after creation: /foundry:manage update <name> "change model to sonnet".
foundry:curator returns low confidence during /foundry:audit
Audit re-runs agent with specific gap named in Gaps: field. Confidence still below 0.7 after one retry: gap surfaced with warning in final report for manual review. Recurring gaps: add to foundry:curator antipatterns section: /foundry:manage update foundry-curator "add gap X to antipatterns-to-flag".
jq not found warning during /foundry:audit setup
Check 4 (permissions-guide drift) requires jq. Install: brew install jq on macOS, apt install jq on Linux. Audit continues without — only Check 4 skipped.
/foundry:audit's fix-level question is denied
The guard blocks only audit's fix follow-up until aggregate.md and a valid summary.jsonl exist and Step 7 delivers the Audit Report, exact Total, and every finding. A valid empty summary permits a zero-finding audit. Recovery questions remain available. Finish the producer, print the required current output, then retry the workflow follow-up. Existing sentinel expiry remains unchanged; it is not a completion receipt.
/foundry:profile's drill-down question is denied
The guard blocks only the profile follow-up until its report exists and the follow-up call's first question text is a short plain summary (report path, Title, Outcome/Verdict; at most 1,500 characters, no table). Diagnostic and recovery questions remain available. Print the required report header, then retry the follow-up.
🏗️ Plugin structure
plugins/cc_foundry/
├── .claude-plugin/    plugin.json (version + metadata), env-defaults.json, permissions-{allow,deny}[-retired].json merged by /foundry:setup
├── agents/            10 specialist agent files (flat — a nested `agents/<x>/y.md` would register as a dispatchable agent)
├── references/        agent sidecar fragments (`references/<agent>/*.md`), loaded on demand; outside `agents/` so never scanned as agents
├── skills/            11 skill directories (audit, brainstorm, calibrate, create, distill, humanizer, investigate, manage, profile, session, setup)
├── rules/             18 rule files symlinked to ~/.claude/rules/foundry-*.md by /foundry:setup (+ on-demand bodies in rules/_full/)
├── hooks/             hooks.json registrations + Node hook scripts and hooks/lib/
├── bin/               Python helpers used by skills and hooks (see Bin helpers below)
├── assets/images/     animated SVG execution diagrams embedded in this README
├── CLAUDE.src.md      workflow rules + the five delivery principles; /foundry:setup Step 10 copies → ~/.claude/CLAUDE.md
├── TEAM_PROTOCOL.md   AgentSpeak v2 inter-agent protocol
└── permissions-guide.md  annotated allow/deny reference (copied to .claude/ by /foundry:setup)
Hooks register through hooks/hooks.json (${CLAUDE_PLUGIN_ROOT} paths). All hooks fail open unless noted: a hook that crashes grants nothing and falls back to normal permission handling.
| Hook | Purpose |
|---|---|
agent-router.js |
PreToolUse Agent: 3-tier fallback routing when an agent name does not resolve |
allow-dispatch.js |
PreToolUse Bash: the one registered auto-allow hook; asks the decision modules in rank order and logs the verdicts |
approval-guard.js |
Records your Approve answers as grants/tokens; blocks agent writes to approval records |
artifact-guard.js |
Feedback on .reports/ and .temp/ Markdown size and density; never blocks |
audit-close.js |
Appends completion and session-boundary rows to the auto-allow audit log |
batch-nudge.js |
Reminds an agent after 4 consecutive single read-only tool calls to batch them |
blueprint-allow.js |
Decision module: allows a Bash command that exactly matches a shipped skill blueprint |
commit-guard.js |
Blocks force pushes; spends the single-use push token; --check-grant reports the local Git grant |
enforce-audit-header.js |
Blocks audit's fix follow-up question until the Audit Report is delivered |
enforce-profile-header.js |
Blocks the profile follow-up question until the report header is delivered |
gh-write-guard.js |
Blocks every gh write without a single-use approval of the exact command |
github-read-allow.js |
Decision module: allows commands made only of allowlisted gh reads |
lint-on-save.js |
Runs pre-commit after Write/Edit; async, cross-session lock, 15 s timeout, skips .temp/ |
md-compress.js |
Normalizes Markdown whitespace and table padding on Edit |
report-header-table.js |
Shared check that report headers and follow-up questions carry the required summary |
rtk-rewrite.js |
Transparently rewrites CLI calls for token compression |
rule-inject.js |
Injects agent-spawn.md and git-commit.md on first use; restores the skill contract after compaction |
rules-check.js |
SessionStart: names missing foundry-*.md rule links when setup never ran |
sentinel-read-allow.js |
Decision module: allows sentinel reads and date stamps in read-only compounds |
session-restore.js |
On /clear, injects an unconsumed handover under 30 minutes old |
stale-plugin-check.js |
SessionStart: warns when the loaded plugin copy is orphaned or not the installed one |
statusline.js |
Status bar agent and tool counts |
task-log.js |
Agent/task tracking, timings log, compaction logging, skill-contract preservation, stale worktree sweep |
teammate-quality.js |
TaskCompleted/TeammateIdle teammate output quality gate |
write-guard.js |
Asks before writing untracked CLAUDE.md/AGENTS.md, .claude/settings*.json, .pre-commit-config.yaml, pyproject.toml |
lib/approval-grants.js |
Approval-record scope table, store and single-use spend shared by the guards |
lib/audit-log.js |
Append-only audit record writer used by allow-dispatch.js and audit-close.js |
lib/shell-git.js |
Quote-aware shell lexer used by the git and gh guards |
For per-hook detail see the header comment of each script in hooks/; the repository-level .claude/README.md summarizes the rule and hook inventory.
🧰 Bin helpers
bin/ holds Python helpers (Python 3.10+, no shell scripts) that skills and hooks call; they are workflow support, not additional slash-command skills. Invoke them through the owning skill or with the installed plugin root. Main groups:
- Audit and document checks — the deterministic Layer-1 checks behind
/foundry:audit(cross-reference, layout, fence/tag symmetry, plugin version sync, README drift viacheck_readme_drift.py, orphaned helpers viacheck_orphaned_bin.py, efficiency signals). - Session, install and state — path and plugin-root resolvers, settings merge (
settings_json.py), run-directory creation, append-only ledgers, review-loop recording, compaction gate, spawned-agent deadline reporting (agent_watch.py), stale lock and worktree cleanup, symlink guard. - Reporting, sync and transforms — profile analyzers (
timing_analyzer.py,cost_analyzer.py), blueprint manifest builder, cross-plugin shared-file propagation (propagate_shared.py), code-block extraction, flag parsing. - Auto-allow audit —
verify_blueprint_audit.pyverifies and prunes the audit log (see Auto-allow audit log).
Status labels printed by propagate_shared.py and check_orphaned_bin.py are ASCII, so they work with legacy console encodings such as Windows cp1252.
Plugin manifests accept numeric X.Y.Z versions: unchanged or one patch, minor, or major bump from committed HEAD.
🔄 Upgrade
Then, inside Claude Code:
Re-run /foundry:setup after upgrade required — symlinks point to versioned cache path, go stale after reinstall.
🗑️ Uninstall
Claude Code runs no cleanup hook on uninstall, so nothing /foundry:setup created is removed by claude plugin uninstall or by make clear-all. Remove by hand:
- Settings keys merged into
~/.claude/settings.json(statusLine,permissions.allow,permissions.deny,enabledPlugins,advisorModel,env), if desired. - The
~/.claude/rules/foundry-*.mdsymlinks and~/.claude/TEAM_PROTOCOL.md, which dangle once the plugin cache version is gone.
🧾 Auto-allow audit log
allow-dispatch.js and audit-close.js append one JSON line each per Bash call to ~/.claude/logs/audit/: one file per session (s-<key>.jsonl, the key being a hash of the session id) plus a shared _no-session.jsonl for calls that arrive without one.
- A record names the deciding plugin and hook, the session and tool-call ids, the working directory, the effective decision with its lane and provenance, and both decision modules' own verdicts.
- Command text is never written — only a digest, and for a provenance allow the manifest
srcit matched. The limit:task-log.jsalready writes the first 200 characters of every Bash command intotimings.jsonlunder the sametool_use_id. That text is masked first (env assignments, credential-named values and flags, URL credentials, Bearer values, well-known token prefixes), andtask-log.jstightens the log directory to0700and log files to0600. - With several plugins installed each writes its own rows and nothing coordinates them, so one completed call yields one row per plugin at each end. That is corroboration, not duplication.
RIG_AUDIT=0disables audit writing without changing any permission decision.
python "${CLAUDE_PLUGIN_ROOT}/bin/verify_blueprint_audit.py" verify
python "${CLAUDE_PLUGIN_ROOT}/bin/verify_blueprint_audit.py" prune --older-than 30 --dry-run
verifyexits 1 only when a record's own hash fails to verify; torn framing from concurrent appends and every classification are warnings.record_hashdetects a record that changed after it was written — it is not tamper-evidence, because the same user owns the log, the hooks and the checker.- Read the classifications as observations rather than proof: a call with a decision row and no completion row is reported as
completion-unobservedwhen the session later ended andin-flight-or-hard-killwhen it did not, and neither distinguishes a refusal at the prompt from a deny rule elsewhere or a closer that died. That a tool ran never establishes that a human approved it. pruneis the only component that deletes a log file, is never run by a hook, and never prunes_no-session.jsonlby age — a growing one means the host stopped sending a session id. Nothing schedulesprune.
Records follow the twelve mandatory fields of "Agent Audit Trail: A Standard Logging Format for Autonomous AI Systems", an active individual-submission Internet-Draft that is not endorsed by the IETF and has no standing in its standards process. Deliberate deviations:
outcomeaddspending, because a decision that has not executed yet has no outcome in the draft's vocabulary.trust_levelisplugin/unknownrather than the draft'sL0–L4, because what is observed is which component proposed an allow, not an authentication level.agent_idis<plugin>/<hook>rather than a URI;session_idis the host's id verbatim rather than a UUID.parent_record_idandprev_hashare always null, because this log is not chained — lineage is derived on read instead.
🧪 Development / testing
One runner (pytest) covers both Python bin/ scripts and JS hooks. Current test count: grep -rc 'def test_' plugins/cc_foundry/tests/*.py | awk -F: '{s+=$2} END{print s}'.
Apply pytest markers and conditional skips directly to test functions or existing test classes, as described in the bin authoring guide.
Run locally (requires Python ≥ 3.10 and Node ≥ 18 — run from repo root):
JS hook tests only:
- JS hook tests are subprocess, black-box contract tests: each spawns a real
node <hook>.jswith a JSON payload on stdin and asserts filesystem side-effects (under/tmp/claude-state-<session_id>/) and exit codes. Therun_hookandstate_dirfixtures live inconftest.py. Python is only the orchestrator, so nopackage.jsonornode_modulesis needed. Tradeoff: these tests cover the hook interface contract, not individual JS function internals. - Python
bin/script tests cover the helpers directly, one test module per script underplugins/cc_foundry/tests/. - Tests are grouped in topic subfolders (
audit/,hooks/,paths/,analysis/, …); the hooks suite includes the guards, auto-allow decision modules, audit log, and the shell lexer.
CI runs full test suite on every push to main and on PRs touching plugins/ (see .github/workflows/ci-tests.yml).
📝 Related articles
- Executed, Not Retyped: What 27 Runs Taught Me About Bash Inside Agent Skills (Level Up Coding, Sep 2026): why a model's retyped bash block can differ from the skill's original, measured on AI-Rig's own skills.
- Reviewed Plugin Code Shouldn't Ask Permission (Level Up Coding, Sep 2026): the blueprint-manifest auto-allow and the provenance fix for reviewed plugin code.
🙏 Contributing / feedback
foundry = part of Borda-AI-Rig repository. Suggest improvement or report bug:
- Run
/foundry:brainstorm "your idea"to develop idea before filing - File issue on repository — include output of
/foundry:audit setup+ Claude Code version - Plugin updates reach users via
claude plugin install foundry@borda-ai-rig(update or reinstall);/foundry:setupafterwards only links rules and merges settings
New agent or skill: use /foundry:manage create — handles scaffolding, README sync, MEMORY.md updates automatically.
Review and evidence expectations in the shipped rules/quality-gates.md:
- Cited proof for factual, causal and completion claims; a representative real case alongside TDD; user-authorized behavior unchanged. Mocks are supplementary polishing after real behavior is validated; unavailable real acceptance stays explicit.
- Review limits remain factual process evidence; an out-of-scope extra review needs one explicit user decision with its gap, expected output and stop condition. Declined optional reviews are omitted from findings and action items while factual limits remain disclosed.
- The shared cross-validation protocol requires parent validation at every severity before findings publication, then capped independent critical verification. Review presentation uses role names only and square-bracketed scores, such as
Software engineer [3]. Static proof may settle a claim; unavailable evidence never refutes it, and incomplete feasible work never becomes unconditional approval. - Review outcomes follow the final findings' concrete impact and required repair. Minor changes include bounded correctness, test and compatibility fixes; Major revision requires evidenced material behavioral impact or substantial repair. The verdict cites the controlling finding IDs, while finding counts, CI status and reviewer votes do not set it automatically. Required fixes remain actionable under Minor, and source approval stays separate from verification readiness. Documentation-only corrections and missing or additional tests normally remain Minor unless concrete material consequences or a substantially incomplete required deliverable justify more; missing tests alone do not establish a production bug. These factors inform one combined judgment: high-impact findings can control the verdict and are never diluted by minor items. Use the strongest confirmed consequence as the baseline, account for proven joint effects, and keep severity, source disposition and verification separate. Missing tests no longer receive an automatic High rating; numeric topic discounts require independent calibration before they can determine verdicts.